
Lesson 3 of 4
Inverses and systems
The inverse runs a transformation backwards when that is possible. In practice you solve $\mathbf{A}\mathbf{x} = \mathbf{b}$ by elimination instead of forming the inverse, and nearly singular matrices show why the answer can still be fragile.
Derive and use the 2x2 inverse formula, and say exactly when an inverse exists.
Solve by elimination, and explain why numerical code solves rather than inverts.
Explain in plain words why nearly singular matrices amplify small errors, and what the condition number measures.

Two people talk at once and two microphones record them. Microphone 1 sits nearer the first speaker and picks up 2 parts of voice 1 for every 1 part of voice 2. Microphone 2 hears both voices equally. If the voices are and at some instant, the microphones read
At one instant the microphones read . What were the voices? You need to run the mixing backwards.
Now move microphone 2 so that it hears exactly half as much of each voice as microphone 1: its row becomes . Then is always exactly half of . The second microphone adds nothing new, and no amount of cleverness recovers two voices from what is really one recording. That matrix, , has determinant : it is singular, the fatal case from the determinant lesson.
This lesson is about the first situation: how to undo a transformation when that is possible, how computers actually do it, and why some matrices that can be undone are still dangerous to undo. The second situation, measuring what a singular matrix loses, is the next lesson, on rank and on LoRA.
Undoing a transformation
Before any formula, what does "undo" mean for a matrix?
The inverse of a square matrix , written , is the matrix that undoes it: for every . Doing and then is doing nothing, so , the identity matrix (ones on the diagonal, zeros elsewhere: the matrix that moves nothing). For square matrices the other order works too: . In the transformation widget, the inverse is the morph played backwards.
Some inverses you can guess from the picture:
- Scaling by 2 is undone by scaling by .
- Rotating by an angle is undone by rotating by .
- The shear slides each point to the right by its height; slides it back.
- A reflection is undone by doing it again.
The microphone matrix is not one you can guess, so try it in the widget. It answers the question "does some matrix send the recordings back to the voices?" The blue and coral arrows are the columns of the matrix in the cells, and you can drag their tips. The white dashed arrow is an input , which you can also drag, and the solid white arrow is its image (the readout gives its coordinates). The dashed blue-then-coral path shows built as copies of column 1 plus copies of column 2. The widget starts with the mixing matrix and the voices .
When does an inverse exist? Exactly when . Both directions follow from the determinant lesson.
- If , then flattens space, so whole lines of inputs share each output. Given such an output, there is no way to choose which input to return, so no inverse exists.
- If , nothing is flattened. For a 2x2 matrix, the formula in the next section builds the inverse explicitly. For larger matrices, elimination (later in this lesson) finds the input that lands on each basis vector, and never gets stuck when the determinant is not zero; those inputs are the columns of , as step 4 of the walkthrough showed.
The inverse also has to scale areas back to where they were, so . The mixing matrix and its inverse both have determinant 1, and .
The 2x2 inverse
Guessing works for rotations and shears. For any 2x2 matrix there is a formula you can use by hand. For with ,
In words: swap the diagonal entries, negate the off-diagonal ones, divide every entry by the determinant. The division is exactly where the formula breaks when the determinant is zero.
Go slower: Deriving the 2x2 inverse
The first column of is : the input that sends to . The second column is the input that sends to . So we solve two small systems.
First column. Find with
To get rid of , make its coefficient the same in both equations. Multiply (1) by : . Multiply (2) by : . Subtract the second from the first; the terms cancel: To get rid of instead, multiply (1) by : . Multiply (2) by : . Subtract the first from the second; the terms cancel:
Second column. Find with
The same two moves. To get rid of , multiply (3) by : . Multiply (4) by : . Subtract the second from the first; the terms cancel: To get rid of , multiply (3) by : . Multiply (4) by : . Subtract the first from the second; the terms cancel:
Assemble. Divide each result by (allowed only when it is not zero), and put the two columns side by side:
Check. Multiply by the matrix in the brackets, one row times one column at a time: so dividing by gives exactly .
Back to the microphones, one move at a time. Here , , , .
- The determinant: . It is not zero, so the inverse exists.
- Swap and , and negate and : .
- Divide every entry by the determinant, 1, which changes nothing: .
- Apply it to the recordings, one row at a time:
The voices were and , as the widget showed. Check by mixing them again: and . The second arrangement, , has determinant 0, so step 3 would divide by zero, and there is no inverse.
Now invert one yourself. This matrix has a negative determinant, which is where most slips happen.
Find for with the swap, negate, divide recipe. Enter the four entries row by row; decimals or fractions (such as -1/2) both work. Before you check, multiply by your answer and see whether you get .
One entry per box, row by row (Tab moves along a row). 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
A practice set builds the habit: swap, negate, divide, then check by multiplying. About half the items ask which input lands on a given output instead; apply the inverse to that output, as you did for the microphones.
Solve for and . In words: which input does send to ?
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
In short: an inverse exists exactly when the determinant is not zero, and for a 2x2 matrix it is "swap, negate, divide by the determinant".
Solving
The microphone question is really a system of equations, and for large matrices nobody writes down the inverse to answer it. This section shows the method people and computers actually use.
The question is: which input lands on ? There are two ways to picture it.
- Column picture. From module 2, . So solving means finding the combination of the columns that makes , exactly the coefficient problem from module 1. For the microphones, . This is the dashed path from the widget.
- Row picture. Each equation is a line in the plane: and . The solution is the point on both lines, where they cross, at . When the lines are parallel: either they never meet (no solution) or they are the same line (infinitely many).
The inverse gives a formula, , but the method people and computers use is elimination: subtract a multiple of one equation from another to remove a variable, repeat until the system is triangular (each equation has one fewer unknown than the one above it), then solve from the bottom up, which is called back substitution. For the microphones:
- The equations are (1) and (2) .
- To remove from (2), subtract the right multiple of (1). Equation (2) has and equation (1) has , so the multiplier is . Half of (1) is .
- Subtract it from (2), term by term:
- Back substitution: put into (1). Then , so and .
Why is this allowed? Combining true equations gives true equations, so every solution of the old system solves the new one. And each step can be undone by adding the multiple back, so the new system has no extra solutions either. The solution never changes, while the matrix becomes triangular. These are the same row shears that computed determinants in the last lesson.
One practical detail. If a zero sits where you need to divide, swap two equations. In fact software swaps whenever a larger entry is available lower down in the same column (partial pivoting), because dividing by a tiny number blows up rounding errors. You will see that happen in the code exercise below.
Now solve a new system both ways, and check it with the column picture.
Solve the system
- By elimination: subtract a multiple of the first equation from the second to remove , solve for , then substitute back.
- With the inverse: write the system as , find with the 2x2 formula, and compute .
- Check your answer in the column picture: which combination of the columns of makes ?
Enter and then in the check.
Work it on real paper: writing each step is the point. Then check your final answer here and compare your working with the walk-through.
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
Solve, do not invert
On paper and "solve " are the same thing. In numerical code they are not, and np.linalg.solve(A, b) beats np.linalg.inv(A) @ b on both counts that matter.
- Cost. Solving factors by elimination once, about multiply-adds for an matrix, then back-substitutes for about more. Forming the full inverse takes about multiply-adds, roughly three times as much, before you even multiply by . (For many right-hand sides, pass them all as the columns of a matrix:
np.linalg.solve(A, B)reuses one factorization.) - Accuracy. When is close to singular, the inverse route loses more accuracy. The run below shows it on a famously difficult family of matrices.
The code builds Hilbert matrices of sizes 4 to 12, picks right-hand sides whose exact answer is all ones, and solves each system both ways. For each it prints the condition number (a measure of how close to singular the matrix is, explained in the next section), how well each answer satisfies the equations, and how far each answer is from the truth.
Read the columns. The residual says how well the answer satisfies the equations. With solve it stays below , the limit of double precision, at every size; with the inverse it grows by many orders of magnitude as the size goes up. The error is the distance from the true answer, and it grows for both methods as the condition number grows. That second effect is not a flaw of either method. It is the matrix itself amplifying rounding errors, and it is the subject of the next section.
Now build both tools yourself: the formula for 2x2 matrices, and elimination for any size.
Build both ways of undoing a matrix.
inverse2(M)returns the inverse of a 2x2 matrix from the formula, as a numpy array, and raisesValueErrorwhen the determinant is 0.solve(A, b)solves for any square by Gaussian elimination with partial pivoting, followed by back substitution, without forming an inverse. It must not change its inputs, and it raisesValueErrorwhen is singular.
Partial pivoting means: before eliminating below the diagonal in column , swap up the row (at or below row ) whose entry in column is largest in absolute value. It fixes zero pivots and, just as important, avoids dividing by tiny ones. One test is designed to catch a solver without it. The tests compare your solve with np.linalg.solve.
raise NotImplementedError, then press Run tests. Each check says what it expects.Nearly singular matrices
In exact arithmetic a matrix is either invertible or not. But real numbers come from measurements and are stored with rounding, and the trouble lives in between: matrices that are invertible, but only just.
An example, step by step. Take and . Its determinant is : not zero, but small.
- Subtract the first equation from the second: , which leaves , so .
- Back substitution: , so . The solution is .
Now nudge the second measurement by , to .
- The same subtraction leaves , so .
- Then , so . The solution is .
A change of 0.001 in one number, about 0.05% of it, moved the answer from to .
The row picture shows why. The two equations are nearly parallel lines, crossing at a very shallow angle, and shifting one of them a hair slides the crossing point a long way along the other.
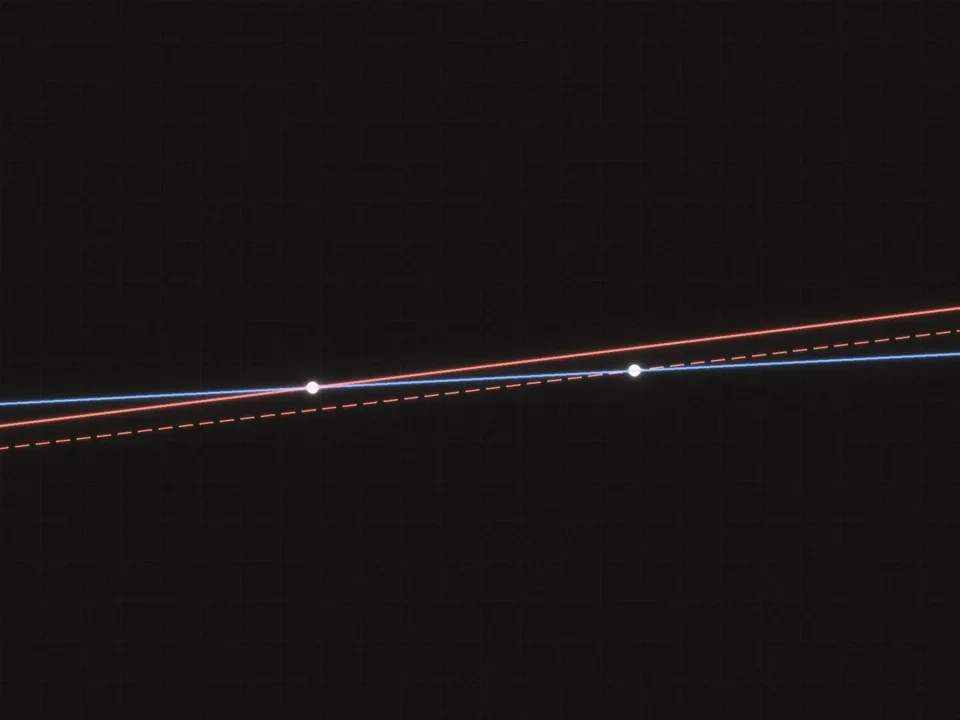 Nearly parallel lines: a tiny shift of one line moves the crossing point, the solution, a long way.
The column picture says the same thing another way. The columns and point in almost the same direction, so producing a small change in across that direction takes a huge, lopsided combination of them.
The condition number. Say a matrix stretches a direction by the factor for a vector pointing that way. The condition number (the Greek letter kappa) is the most stretches any direction divided by the least it stretches any direction. For our matrix:
- The direction is stretched by about 2: , about twice as long as .
- The direction is almost crushed: , whose length is 0.001, while has length . So this direction is stretched by : it comes out about 1,400 times shorter.
These two directions alone give a ratio of about . The most and least stretched directions are not exactly these two but lie less than 0.02° away from them, and at the least stretched one the stretch drops to about 0.0005 (with the direction squeezed this hard, even that tiny tilt changes the stretch a lot). The most stretch is still about 2, so ; computed exactly, . Module 4 shows how to find the exact directions.
Why does this ratio matter? A relative error in (the size of the error divided by the size of ) can be amplified by up to times in . As a rule of thumb, you lose about of the roughly 16 significant digits that double precision carries: here about 3.6 digits. For the Hilbert matrices earlier, at size 10, so about 13 digits are lost, and even solve kept only three or four correct digits.
The run below makes the amplification visible. It adds 300 small random nudges to , solves each time, and plots the nudged right-hand sides next to the solutions they produce.
The right-hand sides form a small round cloud around . The solutions form a long thin streak through along the direction , the direction the matrix barely stretches: a small nudge in needs a big move along that direction to produce it. The worst amplification printed comes out at about the condition number, 4,002, which is the worst case.
As the lesson on computing determinants warned, the determinant does not measure this: in 100 dimensions has a determinant of and condition number 1, while a shear with determinant 1 can have a condition number in the millions.
To recap: a nearly singular matrix squeezes some direction almost flat, so undoing it has to blow that direction back up, and any error along it is blown up too. The condition number measures how lopsided the stretching is, and so how much errors can grow.
Now watch the amplification happen by hand, on a slightly different nearly singular system.
The matrix with gives . Now the second measurement is off by : . Solve again, by elimination as in the lesson. Enter as a column: in the top box, in the bottom box. Decimals are fine.
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
Invertible matrices can be undone, and this lesson showed how, and when to be careful. The next lesson turns to matrices that cannot be undone at all: how many dimensions they keep, what they crush, and why keeping only a few dimensions on purpose is the idea behind LoRA.