Apply a matrix again and again and every vector splits into eigen-directions, each multiplied by its own eigenvalue at every step. That one fact explains diagonalization, power iteration, stability, and why recurrent networks struggle to learn from the distant past.
About 80 minutes
By the end you can
Compute Akx by writing x in the basis of eigenvectors.
Derive A=PDP−1 and Ak=PDkP−1, and read them as a change of basis.
Predict from the spectral radius whether repeated multiplication decays, explodes or sits on the edge, and know when that prediction needs care.
Implement power iteration and explain why it finds the dominant eigenvector, and how fast.
Explain why the eigenvalues of a recurrent weight matrix decide whether gradients vanish or explode.
Here are two matrices that look almost the same:
W1=[0.60.50.50.6],W2=[0.50.40.40.5].
Every entry of W2 is 0.1 smaller. Start both at x=(1,0) and multiply by the matrix 50 times. W150x≈(58.7,58.7), a vector of length about 83. W250x≈(0.0026,0.0026), a vector of length about 0.0036. After 50 steps one result is roughly 23,000 times longer than the other.
The explanation is in the eigenvalues. Both matrices have the eigenvectors (1,1) and (1,−1):
W1(1,1)=(1.1,1.1) and W2(1,1)=(0.9,0.9), so along (1,1) the eigenvalues are 1.1 and 0.9.
Both send (1,−1) to (0.1,−0.1), so along (1,−1) both multiply by 0.1, and that part of x is gone after a few steps.
And 1.150≈117 while 0.950≈0.0052. (The start (1,0) is half of (1,1) plus half of (1,−1), which is where 58.7≈117/2 and 0.0026≈0.0052/2 come from; the first section below shows that move.) A small difference in an eigenvalue becomes an enormous difference after many steps.
A recurrent network does this kind of repeated multiplication, both when it carries information forward through a sentence and when its training signal travels backward. This lesson makes the idea precise, and it is the most important link in Part 1: the eigenvalues you meet here return as vanishing and exploding gradients in module 7 and as the reason the LSTM's cell state works in module 8.
The plan: first watch what a matrix does to each eigen-direction on its own; then write that as a formula for every power (diagonalization); then ask which direction wins in the long run; and finally connect it to recurrent networks.
The whole lesson rests on one move: split the starting vector into eigenvectors, because the matrix treats each piece separately. Let us see that with numbers.
Take B=[0.80.40.20.6]. It is the matrix A=[4213] from the previous lesson divided by 5. Dividing a matrix by 5 divides every output by 5: if Av=λv, then 51Av=5λv. So B has the same eigenvectors, v1=(1,1) and v2=(1,−2), with eigenvalues 5/5=1 and 2/5=0.4. Start from x=(3,0).
Step 1: write x in eigenvectors. We want numbers c1,c2 with c1(1,1)+c2(1,−2)=(3,0). The left side is (c1+c2,c1−2c2), so matching entries gives two equations:
c1+c2=3,c1−2c2=0.
The second says c1=2c2. Put that into the first: 2c2+c2=3, so 3c2=3 and c2=1. Then c1=2c2=2. Check: 2(1,1)+1(1,−2)=(2+1,2−2)=(3,0).
Step 2: apply B once, using linearity.B acts on each piece separately, and each piece is an eigenvector, so each piece is only multiplied by its eigenvalue:
Bx=2Bv1+1Bv2=2(1)v1+1(0.4)v2=(2,2)+(0.4,−0.8)=(2.4,1.2).linearityBvi=λiviwrite out the vectors
Direct check: B(3,0) is 3 times the first column, 3(0.8,0.4)=(2.4,1.2).
Step 3: repeat. The result is again 2 of v1 plus some amount of v2, so the next application does the same thing: the first coefficient is multiplied by 1 again and the second by 0.4 again. After k steps,
Bkx=2(1)k(1,1)+(0.4)k(1,−2)=(2+0.4k,2−2⋅0.4k).
k
0.4k
Bkx
0
1
(3,0)
1
0.4
(2.4,1.2)
2
0.16
(2.16,1.68)
3
0.064
(2.064,1.872)
large
→0
→(2,2)
The component along (1,−2) fades away. The component along (1,1) stays exactly as it was. No matrix multiplication was needed after the first step: once you know the eigen-coordinates, you know every power.
Go slower: Why the formula holds for every k
For one step, use linearity and then the definition of an eigenvector:
The result is again a combination of the same eigenvectors, with new coefficients ciλi. So suppose the formula holds after k steps, Akx=∑iciλikvi. Apply A once more with the same reasoning, now with coefficients ciλik:
It holds for k=1, and each step carries it to the next, so it holds for every k.
Read the formula for what it says about the long run. Each term is multiplied by λi at every step, so:
A component with ∣λ∣<1dies: λk→0.
A component with ∣λ∣>1explodes: ∣λ∣k→∞.
A component with ∣λ∣=1keeps its size. With λ=1 it stays put; with λ=−1 it flips sign every step.
The largest ∣λ∣ wins. After enough steps the term with the biggest ∣λi∣ dwarfs the others, so Akx points along that eigenvector, provided x had some component along it to begin with.
The instrument below runs this experiment and draws it. It multiplies a start x0 by the matrix again and again. On the plane, each xk is drawn at length 1 on the circle, so it stays on screen however long it gets, with a fading trail of earlier steps; the two lime lines are the eigen-directions, and the brighter one has the larger ∣λ∣. The readouts and the chart under the plane keep the true length ∣xk∣, on a log scale.
It starts from x0=(0,1), which is 31(1,1)−31(1,−2) (check: (31−31,31+32)=(0,1)). The instrument scales v1 and v2 to length 1, so its formula shows c1=2/3≈0.47 and c2=−5/3≈−0.75: the same split, measured against unit-length eigenvectors.
The edits in steps 4 and 5 use a handy fact: adding cI to a matrix adds c to every eigenvalue and keeps the eigenvectors, because (A+cI)v=Av+cv=λv+cv=(λ+c)v.
The widget always started from a vector with some of each eigenvector in it. Which starting vectors lose everything instead? Decide from their eigen-coordinates.
Quick checkWhich starting vectors fade
Let B=[0.80.40.20.6], with eigenvector (1,1) for λ=1 and (1,−2) for λ=0.4. Starting from which vectors does Bkx shrink all the way to 0 as k grows? Select every one.
The three steps above work, but they are a recipe in words. Written as three matrices they become a formula, and the formula turns every power of a matrix into powers of plain numbers.
Put the eigenvectors side by side as the columns of a matrix P, and the eigenvalues, in the same order, on the diagonal of a matrix D (zeros everywhere else). For our B:
P=[111−2],D=[1000.4].
The definition Avi=λivi, written for all columns at once, is AP=PD (the box below checks this column by column). If the eigenvectors are independent, P has an inverse (a square matrix with independent columns is invertible, from rank and low-rank updates), and multiplying both sides on the right by P−1 gives
A=PDP−1.
This is diagonalization.
Go slower: Why A P = P D, column by column
The column view of matrix multiplication says that column i of AP is A times column i of P, which is Avi.
Column i of PD is P times column i of D. That column of D is all zeros except λi in position i, so P times it picks out λi times column i of P, which is λivi.
So "AP=PD" says "Avi=λivi for every i". Now multiply both sides on the right by P−1: APP−1=PDP−1. Since PP−1=I, the left side is AI=A, so A=PDP−1.
Read it right to left, as a change of basis. In span, basis and coordinates you saw that the coordinates of a vector depend on the basis you measure it in. Applying A=PDP−1 to x means applying P−1 first, then D, then P:
P−1x gives the coordinates c=(c1,c2) of x in the eigenvector basis. The reason: c1v1+c2v2 is Pc (the columns of P added up in the amounts c), so x=Pc and c=P−1x.
Dc scales each coordinate by its eigenvalue. In this basis the matrix is just a list of independent stretches.
P turns the scaled coordinates back into an ordinary vector.
These are Steps 1 to 3 of the previous section, written as matrices. The diagram below makes the three moves with B and x=(3,0), the same numbers as before. It shows the plane, with the v1 family in lime and the v2 family in teal, and beside it (below it on a phone) the vectors and the matrices P, D and P−1, colored to match. Each step lights up what is new in lime, and the text under the figure writes out that step's arithmetic.
Powers only touch the middle. Step 5 of the diagram used a cancellation. Here it is one move per line:
A2=(PDP−1)(PDP−1)=PD(P−1P)DP−1=PDIDP−1=PD2P−1two copiesregroup (matrix products are associative)P−1P=II changes nothing, and DD=D2Go slower: The general power
Write Ak as k copies of PDP−1 side by side:
Ak=(PDP−1)(PDP−1)⋯(PDP−1).
Matrix multiplication is associative, so we may regroup freely. Every P−1 that sits against the next P becomes I and disappears. There are k−1 such meeting points, and what remains is the first P, the k copies of D, and the last P−1:
Ak=PDkP−1.
Powers of a diagonal matrix are easy, because multiplying two diagonal matrices multiplies matching diagonal entries and leaves zeros elsewhere. For example
D2=[λ100λ2][λ100λ2]=[λ1200λ22],
and in general Dk has λ1k,…,λnk on its diagonal.
A worked example
For A=[4213] with eigenvalues 5 and 2, the eigenvectors (1,1) and (1,−2) give
P=[111−2],D=[5002].
Invert P. The 2x2 inverse formula from module 3 swaps the diagonal entries, negates the other two, and divides by the determinant. Here detP=(1)(−2)−(1)(1)=−3, so
P−1=−31[−2−1−11]=[2/31/31/3−1/3].
Raise D to the power.D3 has 53=125 and 23=8 on its diagonal. Multiplying P on the right by a diagonal matrix scales its columns, so PD3 is the first column times 125 and the second times 8:
PD3=[1251258−16].
Multiply by P−1. Each entry of A3=(PD3)P−1 is a row of the left matrix dotted with a column of the right one:
So A3=[86783947]. Check by brute force: A2=[16+28+64+32+9]=[1814711], and then
A3=A2A=[72+1456+2218+2114+33]=[86783947].
For A100 the eigen route is the same work as for A3, apart from raising two plain numbers to the 100th power, while multiplying one factor at a time costs 99 matrix products.
To recap: writing x in the eigenvector basis turns Akx into c1λ1kv1+c2λ2kv2, and the same fact for the whole matrix is Ak=PDkP−1. Either way, a power costs one change of basis and a few powers of plain numbers.
Diagonalization also runs in reverse: choose the eigenvectors and eigenvalues you want, and PDP−1 builds the matrix that has them.
Work it outBuild a matrix from its eigenvectors
A 2x2 matrix has eigenvector (1,0) with eigenvalue 2 and eigenvector (1,1) with eigenvalue 3. Build it as PDP−1 and enter the four entries of the matrix. They are whole numbers.
A
One entry per box, row by row (Tab moves along a row). 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
Now use the eigen route for a power you would not want to compute by brute force.
On paperThe tenth power by hand
Let A=[0211] and v=(1,5). Compute A10v by hand, without multiplying ten matrices.
Find the eigenvalues and eigenvectors of A.
Write v as a combination of the eigenvectors.
Use the powers formula.
Enter the result below as a column. Both entries are whole numbers.
Work it on real paper: writing each step is the point. Then check your final answer here and compare your working with the walk-through.
A^10 v, as a column
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
When there is no eigenbasis
Diagonalization needed n independent eigenvectors. Two cases from the previous lesson do not have them in real numbers.
Defective matrices. The shear S=[1011] has only one eigen-direction, so there is no invertible P and no diagonalization. Its powers are easy to find directly:
S2=[1011][1011]=[101+11]=[1021],
and each further factor adds 1 to the corner, so Sk=[10k1]. The eigenvalue is 1, yet Sk(0,1)=(k,1) grows without bound, linearly in k. Defective matrices are rare in practice (nudge the entries by tiny random amounts and the result is almost surely diagonalizable), but they show that eigenvalues of size exactly 1 do not settle the question.
Complex eigenvalues. Diagonalization still works if P and D are allowed complex entries, and λk still has modulus ∣λ∣k. For a scaled rotation (rotate by an angle θ and scale by r), k applications rotate by kθ and scale by rk. The direction keeps turning, and the length is governed by ∣λ∣=r.
In every case, the sizes ∣λi∣ decide growth. That leads to one number.
#Who wins: the spectral radius and power iteration
Every component is multiplied by its own λ at every step, so in the long run the only question is which ∣λ∣ is largest. That size gets a name, and the same "largest wins" fact becomes an algorithm.
The spectral radius of a square matrix is the largest eigenvalue size:
ρ(A)=imax∣λi∣,
where ∣λ∣ is the absolute value for a real eigenvalue and the modulus for a complex one. It sorts the long run into three cases:
ρ(A)<1: Akx→0 for every x. (This holds even for defective matrices, where the argument needs more machinery than we have built.)
ρ(A)>1: ∣Akx∣ grows without bound for almost every x. The exceptions are the vectors with no component at all along any eigen-direction whose ∣λ∣ is above 1, and a randomly chosen vector essentially never is one.
ρ(A)=1: the eigenvalues alone do not decide. A rotation keeps every length, the shear grows linearly, and B above settles down to a fixed vector.
Go slower: The powers of C, line by line
Split C into a multiple of I plus the rest: C=0.5I+N with N=[0030]. Two facts make the powers easy. First, N2=[0030][0030]=0. Second, I commutes with everything, so IN=NI=N.
Claim:Ck=0.5kI+k⋅0.5k−1N. At k=1 it reads 0.5I+N, which is C.
One more factor. Suppose the claim holds for k and multiply by C=0.5I+N, expanding the four products:
The last term is zero because N2=0. The two middle terms add to (k+1)0.5kN. So Ck+1=0.5k+1I+(k+1)0.5kN, which is the claim for k+1.
Apply it to (0, 1).I(0,1)=(0,1) and N(0,1)=(3,0), so Ck(0,1)=0.5k(0,1)+k0.5k−1(3,0)=(3k⋅0.5k−1,0.5k). At k=10 that is (30/512,1/1024)≈(0.059,0.001), of length about 0.06.
Power iteration
The "largest wins" rule is also an algorithm. To find the dominant eigenvector (the one whose eigenvalue has the largest size), start from almost any vector and keep multiplying by A, rescaling to length 1 after every step. This is power iteration:
xk+1=∣Axk∣Axk.
Why it works: factor λ1k out of the powers formula, where λ1 is the dominant eigenvalue (we assume it is strictly larger in size than every other eigenvalue),
Akx=λ1k(c1v1+c2(λ1λ2)kv2+⋯).
Every ratio ∣λi/λ1∣ is below 1, so everything in the bracket except c1v1 fades, with the slowest term shrinking like ∣λ2/λ1∣k (here λ2 is the second-largest in size). The factor λ1k in front only changes the length, and the rescaling removes it, which also stops the numbers from overflowing or underflowing.
Once xk is a unit eigenvector, the eigenvalue can be read off with one dot product. Axk=λ1xk, so xk⋅(Axk)=λ1(xk⋅xk)=λ1, because a unit vector dotted with itself is 1. This estimate keeps the sign of λ1, which a ratio of lengths would lose.
Watch it on A=[4213] from (1,0), skipping the rescaling so the numbers stay whole. Each row is the previous one times A; for example A(18,14)=(72+14,36+42)=(86,78). The direction is measured by the slope y/x, which should approach 1, the slope of (1,1):
k
Ak(1,0)
slope y/x
distance from 1
0
(1,0)
0
1
1
(4,2)
0.5
0.5
2
(18,14)
0.778
0.222
3
(86,78)
0.907
0.093
4
(422,406)
0.962
0.038
5
(2094,2062)
0.985
0.015
Divide each distance by the one before: 0.5/1=0.5, then 0.222/0.5≈0.44, 0.093/0.222≈0.42, 0.038/0.093≈0.41 and 0.015/0.038≈0.40. The factor approaches 0.4, which is ∣λ2/λ1∣=2/5. When the top two eigenvalues are close in size, that factor is close to 1 and convergence is slow. When c1=0 it fails, though a random start almost never has c1 exactly zero. And when the dominant eigenvalues are a complex pair, the direction keeps rotating and never settles.
To recap this section: the spectral radius ρ=max∣λ∣ decides the long run (decay below 1, explosion above 1, no verdict at exactly 1), the first few steps can still grow even when ρ<1, and power iteration turns "the largest wins" into a way to find the winner, gaining a factor ∣λ2/λ1∣ per step.
Now write the tools of this lesson in code: power iteration, powers through PDkP−1, the spectral radius and a stability verdict.
Code itPower iteration and a stability check
Build the tools of this lesson.
power_iteration(A, x0, steps): multiply, rescale to length 1, repeat. Return the estimate λ=v⋅(Av) and the unit vector v.
matrix_power_eig(A, k): Ak=PDkP−1, with P and the eigenvalues from np.linalg.eig.
spectral_radius(A): ρ(A)=maxi∣λi∣.
stability(A): the long-run verdict from ρ(A): 'decays', 'explodes' or 'borderline'.
Do not call np.linalg.matrix_power inside your functions; the tests use it to check you.
⌘+Enter runsPython sleeps until you run code
Write your code where the starter says raise NotImplementedError, then press Run tests. Each check says what it expects.
For fluency with the powers formula, here is a practice set with fresh matrices each time.
Practice setPowers reps
3 correct in a row completes the set. A miss starts the count again.
The matrix A=[101.5−0.5] has eigenvectors p1=(−1,1) with λ1=−21 and p2=(1,0) with λ2=1. Use them to compute A9v for v=[3−2]. Give each entry to 2 decimal places.
A^9 v
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
Everything so far was about one matrix multiplying a vector again and again. A recurrent network does exactly that, and the eigenvalues decide whether it can learn from anything but the last few steps.
Module 7 builds a recurrent neural network (RNN). It reads a sequence one step at a time and keeps a hidden state ht, a vector updated by the same weight matrix W at every step:
ht=tanh(Wht−1+Uxt+b),
where xt is the input at step t, U and b are more learned numbers (module 7 names the two matrices Whh and Wxh), and tanh squashes each entry into (−1,1). To train it, we need to know how the loss depends on early states, and backpropagation through time will derive that each step backward multiplies the gradient by W⊤ and by a diagonal matrix of tanh slopes. Going k steps back means k such factors.
Set the tanh slopes aside for a moment (they are at most 1). The core is then (W⊤)kg for a gradient vector g. W⊤ has the same eigenvalues as W:
det(W⊤−λI)=det((W−λI)⊤)=det(W−λI).
The first step uses I⊤=I, so (W−λI)⊤=W⊤−λI; the second uses the fact that a matrix and its transpose have the same determinant. Same characteristic polynomial, same eigenvalues. So everything in this lesson applies: a gradient from k steps back is scaled by roughly ρ(W)k.
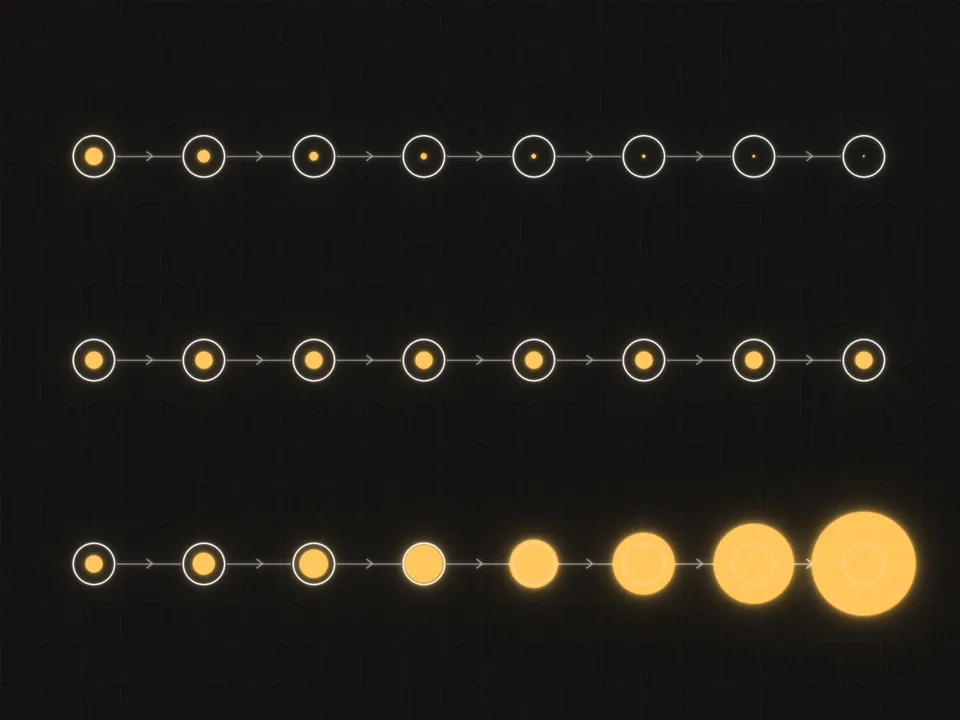
The same factor at every step: a little below 1 and the signal fades away, exactly 1 and it holds, a little above 1 and it explodes.
Here is that experiment with a random 64×64 matrix. The code rescales it so its spectral radius is exactly 1, then multiplies it by 0.9, 1.0 and 1.1, sends the same random gradient back 100 steps through each, and plots the gradient's size after each step, as a multiple of its starting size, on a log scale.
⌘+Enter runs · edit freelyPython sleeps until you run code
Because each W is ρ times the same matrix G, (W⊤)kg is exactly ρk times the ρ=1 result. So read the ρ=1 line first. Over the first 30 or so steps it falls, with some wobble, from 1 to about 0.45, as the parts of the gradient along eigenvectors with smaller ∣λ∣ die out. After that it stays in a narrow band, between about 0.33 and 0.46. It does not sit perfectly still because the two largest eigenvalues of this random matrix are a complex pair, both of modulus 1: the part of the gradient that survives keeps turning inside a plane, and its length wobbles as it turns. At step 100 it happens to be 0.43.
The other two lines are that same curve tilted by log10ρ per step, about −0.046 for 0.9 and +0.041 for 1.1. Over 100 steps the tilt is a factor of 0.9100≈0.000027 on one side and 1.1100≈13,800 on the other. That is exactly how the two printed numbers relate to 0.43: 0.43×0.000027≈0.000011 and 0.43×13,800≈5,900.
Neither extreme is usable. A vanished gradient means the network gets no signal about how its early inputs affected the loss, so it cannot learn dependencies that far back. An exploded gradient throws the weights into chaos, which is why module 7 clips gradients.
How fast does a factor below 1 erase a signal? Put a number on it.
Work it outHow fast 0.9 erases a signal
In a recurrent network, suppose a gradient component is multiplied by 0.9 at every step back in time. After how many steps is it smaller than 1% of its starting size for the first time? Enter a whole number of steps.
steps
Type a number: 0.25, -2, 3/4 and sqrt(2) all work. Enter checks.
The instrument below runs the same experiment on a small tanh RNN, with 8 hidden units, whose recurrent matrix is ρ times a random orthogonal matrix. (An orthogonal matrix, met properly in the next lesson, keeps every length, so every eigenvalue of this one has size exactly ρ.) On screen is a log-scale chart of the gradient's size against the number of steps back k, relative to its size at the last step T: the white line at 1 means unchanged, the band above it means the gradient grew, and the band below means it shrank. The lime line is the RNN. The readouts give the factor per step and the size after 10, 50 and 60 steps; a slider sets ρ, and a toggle brings in the tanh slopes.
The tanh slopes are between 0 and 1, so they can only reduce the most that a single step can stretch the gradient (the lesson after next makes this precise with singular values). That makes vanishing the more common failure. The fix in module 8 is architectural: the LSTM adds a second path, the cell state, along which the per-step factor is a diagonal matrix of "forget gate" values. A diagonal matrix's eigenvalues are its diagonal entries, and the network learns to hold them close to 1 when it needs to remember, so the gradient along that path neither vanishes nor explodes.
To finish, explain the whole chain of reasoning in your own words, with two concrete networks.
In your own wordsTwo networks, fifty steps
Two recurrent networks are identical except for the recurrent weight matrix. In the first, ρ(W)=0.7; in the second, ρ(W)=1.3. Explain what happens in each to the gradient signal from an input 50 steps in the past, why, and why neither network can easily learn a dependency that long.


 The same factor at every step: a little below 1 and the signal fades away, exactly 1 and it holds, a little above 1 and it explodes.