Most vectors change direction when a matrix acts on them. A few special directions only stretch, shrink or flip. Those eigenvectors, and their stretch factors, predict what a matrix does when you apply it again and again.
About 65 minutes
By the end you can
Recognize an eigenvector from a picture or from one multiplication, and read off its eigenvalue.
Derive the equation det(A−λI)=0 and explain why its roots are the eigenvalues.
Find the eigenvalues and eigenvectors of any 2x2 matrix by hand, and check them with the trace and the determinant.
Tell apart the three cases for a 2x2 matrix: two real directions, a repeated eigenvalue, and complex eigenvalues.
Write a 2x2 eigen-solver in Python and test that its answers satisfy the definition.
Take the matrix
A=[4213]
and feed it a few vectors. Remember from matrices as transformations that Ax is x1 times the first column plus x2 times the second, so here Ax=x1(4,2)+x2(1,3).
A(1,0)=1(4,2)+0(1,3)=(4,2). The input pointed along the x-axis; the output points up and to the right. It turned.
A(0,1)=0(4,2)+1(1,3)=(1,3). The input pointed straight up; the output leans to the right. It turned the other way.
A(1,1)=(4,2)+(1,3)=(5,5)=5(1,1). This one did not turn. It is still on the line through (1,1), five times as long.
A(1,−2)=(4,2)−2(1,3)=(4−2,2−6)=(2,−4)=2(1,−2). Also still on its own line, twice as long.
Of all the directions in the plane, this matrix leaves exactly two alone: the line through (1,1), stretched by 5, and the line through (1,−2), stretched by 2. Those two directions and their two factors are the key to what the matrix does when you apply it over and over.
Why would anyone apply a matrix over and over? A recurrent network, which reads a sentence one step at a time, multiplies by the same weight matrix at every step. Whether its training signal survives 50 steps depends on numbers like 5 and 2.
Module 3 described what one application of a matrix does to space: how it scales area and which dimensions survive. This module asks what happens when the same matrix is applied again and again. This lesson finds the special directions and their factors, first by picture and then by hand. The next lesson shows what they predict.
We found two special directions by trying four vectors. Before any algebra, it helps to see how rare they are among all the directions a vector could point.
The instrument below answers one question: for which directions v does Av land on the same line as v? On screen is the unit circle (every direction, at length 1), a blue arrow v on it, and a white arrow Av for our matrix A. A faint blue line runs through v, and a short dashed drop from the tip of Av shows how far it lands off that line. The dashed ellipse is where A sends the whole circle.
As v goes around, Av swings around faster or slower than v, and twice per half-turn it catches up and lines up with it. Those are the eigen-directions. Here is the precise statement.
What the value of λ says:
λ>1: the vector is stretched along its line.
λ=1: it is left exactly where it is.
0<λ<1: it shrinks along its line.
λ<0: it flips to the other side of the origin, still on the same line, and is scaled by ∣λ∣.
λ=0: it is squashed to the origin.
Three details are worth fixing in place now.
An eigenvector is really a whole line. Suppose Av=λv, and take any number c=0. Linearity lets us pull c out, and then the definition does the rest: A(cv)=cAv=cλv=λ(cv). So (2,2) and (−3,−3) are eigenvectors of our A just as much as (1,1) is. We report one convenient representative, such as (1,1) or the unit vector (1,1)/2.
The zero vector does not count.A0=λ0 holds for every λ, so allowing it would make every number an eigenvalue and the idea would say nothing.
Only square matrices have eigenvectors.Av has to live in the same space as v for "a multiple of v" to make sense, so A must be n×n.
A mirror is a good first test of the definition, because you can see what it does to every direction without computing anything.
Quick checkWhat a mirror keeps
The matrix A=[0110] reflects the plane across the line y=x (it swaps the two coordinates). Picture what the mirror does to each vector below. Which of them are eigenvectors of A? Select every one.
Sweeping works for a picture, and guessing worked for (1,1), but neither is a method. Here is one that always works for a 2x2 matrix, in three moves: rewrite the definition as a statement about one matrix, use what module 3 says about such matrices, then expand.
Move 1: rewrite the definition. Start from Av=λv and change one thing per line.
Av−λvAv−λIv(A−λI)v=0=0=0subtract λv from both sideswrite v as Ivfactor v out on the right
The middle line is needed because you cannot subtract a number from a matrix. I is the identity matrix, with ones on the diagonal and zeros elsewhere; it leaves every vector alone, so Iv=v, and λI is a matrix we can subtract from A.
Move 2: read it with module 3. The last line says that the matrix A−λI sends the nonzero vector v to zero. Module 3 tells us two things about any matrix that does that.
It cannot be undone. It sends both 0 and v to 0, so from the output 0 there is no way to tell which input you started from. It has no inverse (inverses and systems), and v lies in its null space, the set of inputs it sends to 0.
Its determinant is zero. Squashing a whole direction to zero flattens the plane onto a line (or a point), and a flattened square has area 0 (the determinant).
The argument also runs backwards. If det(A−λI)=0, then A−λI flattens the plane onto a line or a point, so two different inputs p and q land on the same output. By linearity their difference v=p−q, which is not zero, lands on that output minus itself, which is 0. That v satisfies (A−λI)v=0, which is Av=λv. So the eigenvalues are exactly the solutions of
det(A−λI)=0.
This is the characteristic equation. Notice that v has dropped out: it is one equation in the single unknown λ. We find λ first and the eigenvectors second.
Move 3: expand it for a 2x2 matrix. Write A=[acbd]. Subtracting λI only touches the diagonal, and the determinant of a 2x2 matrix is "diagonal product minus off-diagonal product":
det[a−λcbd−λ]=(a−λ)(d−λ)−bc=λ2−(a+d)λ+(ad−bc).Go slower: Expanding the determinant, line by line
Multiply out the first product term by term:
(a−λ)(d−λ)=ad−aλ−dλ+λ2.
Subtract bc:
ad−aλ−dλ+λ2−bc.
Group by powers of λ. The λ2 term has coefficient 1. The λ terms are −aλ−dλ=−(a+d)λ. The constant terms are ad−bc:
λ2−(a+d)λ+(ad−bc).
The number a+d is the trace of A, written trA: the sum of the diagonal entries. The number ad−bc is detA. So for every 2x2 matrix,
det(A−λI)=λ2−(trA)λ+detA.
This quadratic is the characteristic polynomial. Its roots, from the quadratic formula, are
λ=2trA±(trA)2−4detA.
The worked example
For A=[4213], the trace is 4+3=7 and the determinant is 4⋅3−1⋅2=12−2=10. The characteristic equation is
λ2−7λ+10=0.
Two numbers that multiply to 10 and add to 7 are 5 and 2, so it factors as (λ−5)(λ−2)=0, and λ=5 or λ=2. The quadratic formula agrees: λ=(7±49−40)/2=(7±3)/2, which is 10/2=5 or 4/2=2.
Now find a vector for each eigenvalue by solving (A−λI)v=0 with v=(x,y).
For λ=5: subtract 5 from each diagonal entry:
A−5I=[4−5213−5]=[−121−2].
The second row is −2 times the first. That is not luck: we chose λ to make this matrix singular, and a singular 2x2 matrix has parallel rows. So there is really one equation, −x+y=0, which says y=x. Taking x=1 gives v=(1,1). Check: A(1,1)=(5,5)=5(1,1).
For λ=2:
A−2I=[4−2213−2]=[2211].
One equation again, 2x+y=0, so y=−2x. Taking x=1 gives v=(1,−2). Check: A(1,−2)=(2,−4)=2(1,−2).
Both match what we found by trying vectors at the top of the lesson.
Two free checks
Hand calculations slip. Two checks catch most slips, and they cost almost nothing. Suppose the two roots are λ1 and λ2. A quadratic whose leading coefficient is 1 factors through its roots, so the characteristic polynomial equals (λ−λ1)(λ−λ2). Multiply that out:
This must be the same polynomial as λ2−(trA)λ+detA, and two polynomials are equal only if their coefficients match. Matching the λ terms, then the constants:
λ1+λ2=trA,λ1λ2=detA.
The eigenvalues add up to the trace and multiply to the determinant. Here 5+2=7 and 5×2=10. The same two facts hold for n×n matrices, summing and multiplying all n eigenvalues (repeated and complex ones included), though we will not prove the general case. The product rule also fits the determinant's meaning: along the two eigen-directions the matrix stretches by 5 and by 2, and areas scale by 5×2=10.
For an n×n matrix, det(A−λI) is a polynomial of degree n, so there are n eigenvalues counting repeats and complex ones. Nobody finds them this way beyond tiny matrices. Numerical libraries, including the LAPACK routines that numpy calls, use iterative methods (the QR algorithm) that never write the polynomial down. The 2x2 hand method is for understanding what the numbers mean.
To recap the method: form λ2−(trA)λ+detA=0 and solve it; for each root, take a nonzero row (p,q) of A−λI and read off the eigenvector (q,−p); then check that the roots add to the trace and multiply to the determinant.
Start with the second half of the method on its own: the eigenvalue is given, and you find its vector.
Work it outFind the eigenvector
One eigenvalue of A=[1322] is λ=4. Find its eigenvector, scaled so that its first entry is 1. Enter it as a column (x,y); decimals are fine.
v
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
Now the whole method, twice, on paper. The second matrix has negative eigenvalues, so watch the signs.
On paperTwo full eigen-decompositions
Find all eigenvalues and eigenvectors by hand. For each matrix, write the characteristic polynomial, solve it, find an eigenvector for each eigenvalue, and check with the trace and the determinant.
A=[62−21]
B=[0−21−3]
Then enter the four eigenvalues below as one column: A's larger, A's smaller, B's larger, B's smaller. (For negative numbers, larger means closer to zero: −1 is larger than −2.)
Work it on real paper: writing each step is the point. Then check your final answer here and compare your working with the walk-through.
The four eigenvalues as a column: A's (larger first), then B's (larger first)
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
For fluency, here is a practice set with fresh matrices every time.
Practice setEigenvalue reps
3 correct in a row completes the set. A miss starts the count again.
Find the eigenvalues of A=[−33−66]. Enter them as a column, largest first.
λ₁, λ₂
One entry per box, top to bottom. 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
The quadratic formula takes a square root, and the number under it can be positive, zero or negative. Each case turns out to be a different kind of matrix. That number, (trA)2−4detA, is called the discriminant.
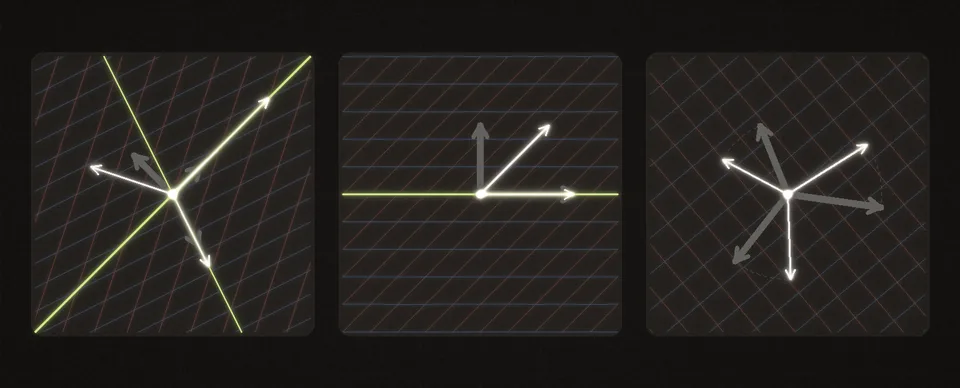
The instrument below shows each case as a picture before we work through the algebra. It is the matrix instrument from module 2: the grid of the plane after the map, the blue and coral arrows where ^ and ^ land (the two columns), and now lime lines along every real eigen-direction, each tagged with its eigenvalue. The readouts give the eigenvalues. Each preset button loads a matrix with a short animation from the identity; let it finish before you read the numbers.
Positive discriminant: two different real eigenvalues. Two separate eigen-directions, as in our example, where the discriminant is 72−4⋅10=49−40=9.
Zero discriminant: one repeated eigenvalue. This case hides two very different pictures.
2I=[2002] has trace 4 and determinant 4, so the discriminant is 16−16=0 and λ=2 twice. Then 2I−2I is the zero matrix, which sends every vector to zero, so every nonzero vector is an eigenvector. The matrix scales everything equally.
The shear S=[1011] has trace 2 and determinant 1, so the discriminant is 4−4=0 and λ=1 twice. But S−I=[0010] gives the single equation y=0: only the x-axis survives. The shear slides each point sideways by its height, so every direction except horizontal gets tilted. A matrix like this, without enough eigenvectors to make a basis, is called defective. It will need special care in the next lesson.
Negative discriminant: no real eigenvalues. The rotation by 90°, R=[01−10], has trace 0 and determinant 0⋅0−(−1)⋅1=1, so the characteristic equation is λ2+1=0. No real number squares to −1. The picture agrees: a rotation turns every vector, so no direction stays on its line.
Algebra still gives an answer if we allow complex numbers. Recall that i is a number with i2=−1, and a complex number a+bi has a size, its modulus, ∣a+bi∣=a2+b2. Then λ2+1=0 has the roots λ=±i, because i2=−1 and (−i)2=−1. Both have modulus 02+12=1.
Those complex eigenvalues still carry information. Take a scaled rotation, a matrix of the form
[ab−ba]:tr=2a,det=a⋅a−(−b)⋅b=a2+b2.Go slower: The eigenvalues of a scaled rotation, line by line
The discriminant is
(2a)2−4(a2+b2)=4a2−4a2−4b2=−4b2.
It is negative whenever b=0. Its square roots are ±2bi, because (2bi)2=4b2i2=−4b2. Put that into the quadratic formula:
λ=22a±2bi=a±bi.
Both roots have modulus a2+b2.
Call that modulus r=a2+b2. Geometrically, a scaled rotation turns every vector by the same angle and scales it by r. To see why, factor r out of every entry:
The matrix on the right is the rotation by θ from matrices as transformations. An angle with that cosine and sine exists because the point (a/r,b/r) lies on the unit circle: (a/r)2+(b/r)2=(a2+b2)/r2=1.
For example, [11−11] (the Rotate + scale preset) has a=1 and b=1, so r=2≈1.414 and cosθ=sinθ=1/2, which means θ=45°. It turns everything by 45° and stretches it by 2, and its eigenvalues are 1±i, of modulus 2: the 1.41 you saw in the readout. For a scaled rotation, the modulus of the eigenvalue is the stretch per step and θ is the turn per step. When we apply a matrix repeatedly in the next lesson, the modulus is what decides growth or decay, whether or not the eigenvalue is real.
For a real matrix, complex eigenvalues always come in pairs a±bi, because the characteristic polynomial has real coefficients.
Two eigen-directions, one, or none: a general stretch, a shear and a rotation.
To recap: the sign of the discriminant sorts every 2x2 matrix. Positive means two real eigen-directions. Zero means one repeated eigenvalue, with either every direction (λI) or just one (a shear). Negative means a complex pair a±bi and no real direction at all, but the modulus a2+b2 still says how much each step stretches.
Now sort some matrices yourself, using the discriminant first and the picture second.
Quick checkNo direction survives
Which of these matrices have no real eigenvector? Decide with the discriminant (trA)2−4detA (negative means no real eigenvalue), then check against a picture of what each matrix does. Select every one.
By hand is for understanding; in practice numpy does the work, with np.linalg.eig. Run this and compare with our hand results.
⌘+Enter runs · edit freelyPython sleeps until you run code
Four things to notice, because each one causes bugs:
Eigenvectors are the columns of V, not the rows. V[:, 0] goes with lam[0].
They are scaled to length 1. The second column, (−0.447,0.894), is (1,−2)/5 with its sign flipped: 1/5≈0.447 and 2/5≈0.894. Both signs are equally valid, and different libraries (even different versions of one library) choose differently.
The order is not guaranteed. Sort them yourself if you need the largest first.
The results can be complex numbers. They always are when some eigenvalue is complex, as for the rotation, and Python writes i as j. Some numpy versions return complex arrays from eig even when every eigenvalue is real, with imaginary parts of zero. When you know the eigenvalues are real, take .real.
Now build the 2x2 solver yourself, from the characteristic polynomial. The tests check behavior, not your particular formulas: eigenvectors are only defined up to scale and sign, so they check Av=λv directly.
Code itA 2x2 eigen-solver
Build an eigen-solver for 2x2 matrices from the characteristic polynomial, then a checker for the definition.
char_poly(A) returns the trace t and the determinant d, so the polynomial is λ2−tλ+d.
eigenvalues_2x2(A) returns both eigenvalues, larger first: plain floats when they are real, a complex pair (positive imaginary part first) when the discriminant is negative.
eigenvector_2x2(A, lam) returns a unit eigenvector for a real eigenvalue, using a row of A−λI as in the lesson. Watch for zero rows.
is_eigenpair(A, v, lam) checks Av=λv and rejects the zero vector.
Use the formulas from the lesson rather than np.linalg.eig; the tests use numpy to check you.
⌘+Enter runsPython sleeps until you run code
Write your code where the starter says raise NotImplementedError, then press Run tests. Each check says what it expects.
Finally, put the central argument of this lesson into your own words.
In your own wordsWhy the determinant equation
Explain to a colleague, without just quoting the formula, why the eigenvalues of A are exactly the numbers λ that make det(A−λI)=0. Use the idea of a matrix squashing space.


 Two eigen-directions, one, or none: a general stretch, a shear and a rotation.