
Lesson 3 of 4
Shapes, transposes and batches
Reading shapes is the skill that prevents most bugs. This lesson builds that habit, introduces the transpose, turns the column vectors of math into the row batches of code, and shows how numpy stretches one bias across a whole batch.
Predict the shape of any product, and spot a mismatch before running the code.
Tell a 1-D numpy array from a row or a column, and reshape between them.
Use the transpose and the rule , and write dot and outer products with it.
Translate between for one column vector and
X @ W + bfor a batch of rows.Apply numpy's broadcasting rules, and find the silent bugs they cause.

Here is one of the errors you will see most often while writing neural network code:
ValueError: matmul: Input operand 1 has a mismatch in its core dimension 0, with gufunc
signature (n?,k),(k,m?)->(n?,m?) (size 4 is different from 10)
It is annoying, but it is the good case: the code stopped and told you. The bad case is code that runs, returns a number, and the number is wrong because two arrays were combined in a way you did not intend. Both kinds of bug come from shapes, and both mostly disappear once reading shapes becomes a reflex.
This lesson builds that reflex in four steps: reading the shape of any product; the transpose, which flips a matrix's rows and columns; moving from the math of one input, a column vector, to the code of many inputs at once, a batch of rows; and broadcasting, the rule that lets numpy add one bias to a whole batch and also causes the quietest bug in this course. The next lesson stacks these layers into networks and counts the numbers behind the phrase "a 7B model".
Reading shapes
Every bug in the opening comes down to two sizes that should have matched, so start with the rule for which sizes must match.
The rule from the last lesson: an matrix times an matrix is an matrix. The inner sizes must match, and the outer sizes survive. In a chain, every neighboring pair must match and only the two ends survive. In , the first pair meets at , the second pair meets at , and the result is .
Vectors fit the same rule once you treat them as thin matrices. A column vector with entries is , and a row vector is . Then:
- A matrix times a vector: , a column with entries.
- A row times a column: , a single number. That is the dot product.
- A column times a row: , a full matrix. That is the outer product from the last lesson.
A worked example. Let be , be , and have 4 entries. Then is : the first pair meets at 3, the second at 4, and the result is . But is , where the inner sizes are 4 and 2, so it does not exist. The question "is equal to ?" can fail before you look at a single number: one side may be undefined, or the two sides may have different shapes.
In numpy every array has a .shape, a tuple such as (2, 3) for 2 rows and 3 columns. One detail causes a lot of confusion, so take it slowly. A 1-D array has a shape with a single number, such as (3,), and it is neither a row nor a column: it has only one axis. The @ operator decides for you what it should be:
- A 1-D array on the right of
@is read as a column, and on the left as a row. - After the product, numpy drops that borrowed axis again.
So a (2, 3) matrix @ a (3,) vector gives shape (2,), not (2, 1), and two 1-D arrays of the same length give a plain number, their dot product. When you need a genuine column, x.reshape(-1, 1) makes it (n, 1) (the -1 tells numpy to work out that size from the others), and x.reshape(1, -1) makes a (1, n) row.
The code below makes each case concrete. With and , the product is . Expect the same two numbers with shape (2,) and then (2, 1), the number for x @ x, and a outer product.
Check that you can predict what numpy does with a 1-D array.
In numpy, A has shape (3, 4) and x = np.ones(4) has shape (4,). What is the shape of A @ x?
Choose one answer, then check.
The transpose
Two jobs in this module need the same tool. Moving between the math and code conventions is a transpose, and so is writing a dot product the way most papers do.
The transpose of a matrix flips it over its main diagonal, the one from top left to bottom right. Rows become columns:
Row 1 of the original, , became column 1, and row 2, , became column 2. An matrix becomes , and flipping twice gets you back where you started: .
The transpose gives compact names to two products you already know. For columns and with entries, is a row, so
With and : , while is the matrix with rows , and , that is , and . Most papers write dot products as , so it is worth recognizing on sight.
The rule you will use constantly is the transpose of a product:
The order reverses, and the shapes show why it has to. Let be and be . Then is , so is . On the right, is and is , so is , a match. The other order, , is , which does not even fit unless .
Go slower: The transpose rule, entry by entry
Left side. First use the definition of the transpose, then the entry rule for products:
Right side. First use the entry rule for the product , then the definition of the transpose for each factor:
Compare. Each term on the left equals the term on the right, since numbers commute. The sums are equal for every and , so the matrices are equal.
Two consequences come up again and again:
- . A matrix acting on a column is the same as the row version of that vector acting on the transposed matrix, from the other side. The next section is built on this line.
- . A matrix is its own transpose, so , using the product rule and then flipping twice. The dot product is symmetric, as module 1 said.
In numpy the transpose is A.T. On a 1-D array .T does nothing at all, since there is only one axis to flip: x.T.shape == x.shape. If you need a row or a column, reshape.
Now check the rule with numbers, and then prove it for yourself.
Let and .
- Compute and its transpose .
- Compute and check that it matches.
- What shape is ? Why can it not be the answer?
- Prove for any shapes that fit, by writing entry of each side as a sum.
To check, enter row by row.
Work it on real paper: writing each step is the point. Then check your final answer here and compare your working with the walk-through.
One entry per box, row by row (Tab moves along a row). 0.25, -2, 3/4 and sqrt(2) all work. Enter moves to the next empty box and checks once all are filled.
From one input to a batch
Every paper writes a layer for one input; every codebase runs it on a batch. This section shows that the two are the same computation laid out differently, so you can move between them without guessing.
In math, and in most papers, a layer acts on one input written as a column: has entries and
where is (one row per neuron, as in Matrices as transformations) and has entries.
In code we process many inputs at once, a batch, and store them as the rows of a matrix with shape : one example per row, the way data arrives in a table. Most numpy and deep learning code puts the batch axis first.
The layer diagram from the first lesson shows both layouts with the same numbers. It opens on step 4: the layer from that lesson, with two neurons reading three inputs, written in the math convention as . Step 5 is the same layer in the code convention.
Here is why the code layout must use . Take example number of the batch as a column, , with output . (Bold is a whole vector, example ; a plain would be one entry.) Transpose both sides of the math, using from the last section and the fact that transposing a sum transposes each term:
Read each side as a row. On the left, is example 's output laid down as a row: row of the output. On the right, is example laid down as a row, which is row of . So row of the output is row of times , plus the bias written as a row. Check it on the diagram's first example. The row times is , and adding the bias row gives . The second example, , gives , plus : , the second row of .
Now stack all the rows. By the row view of a product from the last lesson (row of is row of times ), the whole batch is one matrix product, , with the same bias row added to every row. Code in this convention, including every exercise in this course, stores the weights directly in the transposed layout, shape , and calls that W. So the layer becomes
Y = X @ W + b # X: (batch, d_in) W: (d_in, d_out) b: (d_out,) Y: (batch, d_out)| One input (math convention) | A batch (code convention) | |
|---|---|---|
| Input | , a column with entries | X, shape (batch, d_in), one example per row |
| Weights | , shape | W, shape (d_in, d_out): the math's |
| Layer | Y = X @ W + b | |
| Output | a column with entries | Y, shape (batch, d_out) |
It is the same computation in two layouts. From here on, this course says which convention a formula uses whenever it could be ambiguous. Nothing in the batch mixes examples: row of Y depends only on row of X, and the weights do not depend on the batch size at all. Batching is purely a way to hand the hardware one large matrix product instead of many small ones.
To recap: math writes one input as a column and a layer as ; code stacks inputs as rows and writes X @ W + b, where the code's W is the math's . Before moving on, explain the switch in your own words.
Math writes a layer as for one input. Code writes Y = X @ W + b for a batch. Explain why these are the same computation: what the rows of X and Y are, how the two Ws are related, and what happens to the bias.
Saved in this browser as you type.
Broadcasting: how one bias reaches every row
One piece of X @ W + b has not been explained yet, and it is the source of the quietest bug in this course. X @ W has shape (batch, d_out) and b has shape (d_out,). The shapes differ, yet numpy adds b to every row. The mechanism is broadcasting, and it has three rules:
- Line the two shapes up from the right.
- On each axis, the sizes must be equal, or one of them must be 1. A missing axis counts as 1.
- Every size-1 axis is stretched, by repeating its values, to match the other size.
Walk the bias through the rules with a batch of 32 and 4 outputs. The shapes are (32, 4) and (4,). Lined up from the right, the last axes are 4 and 4: equal, fine. The bias has no first axis, which counts as 1, against 32: stretched, so the bias row is repeated 32 times. The result has shape (32, 4), with the same bias added to every row. The table runs the rules on more pairs.
Shape of a | Shape of b | a + b |
|---|---|---|
(32, 4) | (4,) | (32, 4): b added to every row |
(32, 4) | (1, 4) | (32, 4): the same thing |
(32, 4) | (32, 1) | (32, 4): one number per row, added across that row |
(32, 4) | (4, 1) | error: 32 against 4 |
(8, 1) | (3,) | (8, 3): both stretch, every pair added |
(n, 1) | (n,) | (n, n): the silent bug |
The last row is the classic. A model's predictions often come out as a column of shape (n, 1), while the targets are stored as a flat array of shape (n,). Subtracting them does not fail. Walk through the rules: the flat array's missing first axis counts as 1, so the shapes are (n, 1) and (1, n). On the last axis, 1 meets , so the predictions are repeated across columns; on the first axis, meets 1, so the targets are repeated down rows. Entry [i, j] of the result is prediction minus target : an table comparing every prediction with every target.
With three perfect predictions, against the targets , the true error is 0. The buggy table has rows , and . Its squares add up to , and their mean is : a perfectly plausible number that means nothing.
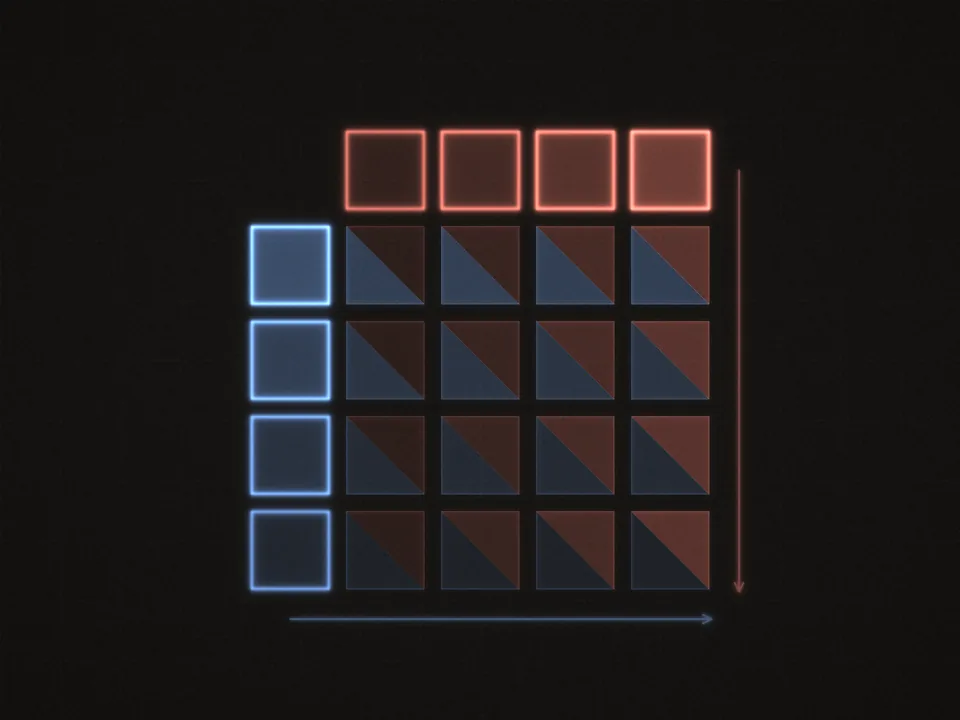 Broadcasting a column against a row: numpy repeats the column across and the row down until both fill a square table. That is how (n, 1) minus (n,) quietly becomes (n, n).
The widget below draws a small two-layer network in the code convention, every block to scale, so you can watch which blocks depend on the batch and see broadcasting at work. On screen: (: 4 examples with 3 features), then @ () + → (), then @ () + → (). Each bias is stored as a single row, and its dashed copies stretched down the batch are the broadcast. The sliders above the figure set the sizes; the readouts count the parameters (every number stored in the s and s, which training will learn; the next lesson counts them properly), the multiply-adds, and the output shape.
Here is the batch layout, the per-example math it replaces, and both kinds of shape bug in code. The loop prints the same rows as Y, one example at a time; the buggy loss prints about 1.33 and the fixed one 0.0; and the last line prints the loud ValueError.
Now read five expressions the way numpy would: inner sizes for each @, and the broadcasting rules for each +.
In code, X has shape (32, 10) (32 examples with 10 features each), W has shape (10, 4) and b has shape (4,). Which expressions produce the layer's output with shape (32, 4)? Select all that work.
Choose every option that applies, then check.
Silent bugs are easiest to recognize once you have fixed a real one. This short pipeline has two.
This small pipeline centers the features, makes predictions with a linear model and computes the mean squared error. It runs without an error and prints a loss, but the loss is wrong. There are two shape bugs.
- Fix
center_featuresso that every column (every feature) ends up with mean 0. - Fix
predictso that it returns shape(n,), one number per example. - Make
mseraiseValueErrorwhenpredandyhave different shapes, so this kind of bug cannot hide again.
Run it first and read the shapes it prints. If you add the guard in mse before fixing predict, the last line stops with your ValueError: that is the guard doing its job.
To recap the lesson: say the shapes before you run anything; a transpose flips rows and columns and reverses products; code runs a batch as X @ W + b with the transposed weights; and broadcasting stretches size-1 axes, which adds the bias to every row and, with an (n, 1) column and an (n,) array, quietly builds an table. Layers and parameter counts puts these layers into networks.